

If you build on models, the August 16 news that Stripe agreed to acquire OpenRouter for more than $7 billion probably looked odd.
Stripe handles payments and billing. OpenRouter routes requests between AI models. Why would a financial infrastructure company spend roughly 5x the $1.3 billion valuation OpenRouter carried after its Series B three months earlier on a model router?
The answer is easier to see from both sides of it
As an OpenRouter user, I’ve been using OpenRouter for about two years, roughly $50 a month on side projects, so nowhere near enterprise scale. As Stigg’s CTO, we spend our days on the other side of the same problem: turning model consumption into something a company can actually sell to customers.
From either side, the deal reads the same way. Stripe is trying to be the bank that every AI company is currently forced to build for itself, and the router is only one part of it.
OpenRouter isn’t really a router
On paper, OpenRouter is very easy to explain.
You send an API request, choose a model, and OpenRouter routes it to one of the providers that can serve that model. Or you can let it make some of those decisions for you based on price, latency, availability, or other parameters.
Today it covers more than 400 models from over 80 providers, and it says it processes more than 10 trillion tokens per day for a community of over 10 million developers and companies.

That is already useful, but routing by itself isn’t a particularly defensible product anymore. Everyone is building routers and gateways.
The more interesting part of OpenRouter is the marketplace underneath it, and the thesis that marketplace was built on: AI neurodiversity, where the future is not one model winning everything but many models competing for different workloads.
Alex came to OpenRouter after co-founding OpenSea, and the marketplace thinking seems to have been there very early. In a recent 20VC interview, he explained that initially they weren’t even sure the inference provider layer itself would become a marketplace. Then companies like the independent inference providers got very good at hosting open models, much faster in many cases than the hyperscalers, and the supply side fragmented.
So OpenRouter ended up sitting between model labs, inference providers and developers.
That’s a much more valuable position than simply having an API proxy.
This is where I think the fit with Stripe becomes obvious.
Stripe is not a marketplace in exactly the OpenSea sense, obviously, but its biggest power has always been marketplace-like aggregation.
As a developer, you don’t really want to separately solve acquiring, payment methods, fraud, currency conversion, invoicing, tax, subscriptions, retries, financing and everything else surrounding a transaction. Stripe puts an API in front of that mess.
OpenRouter did something surprisingly similar for inference.
One integration gives me access to different models, different providers, different prices, different availability characteristics and increasingly different policies around how the models should be used. OpenRouter itself describes the shared DNA pretty explicitly: both companies abstract complicated infrastructure and market dynamics behind developer APIs.
If tokens are becoming an economic primitive inside software, Stripe needs this side of the marketplace too.
The economic power is in breaking the inference moat
There are roughly three ways an AI company consumes inference today.
The obvious one is directly from the model lab. You have an OpenAI or Anthropic account, negotiate some credits or committed spend, and call their APIs.
The second is an inference provider. This is especially common with open models, image models and video models. Someone else takes the model, runs the infrastructure, optimizes it and gives you an API.
The third is running the model under your own control, either much closer to self-hosting or through infrastructure where you control the deployment and economics.
Each option creates a different kind of moat.
The frontier lab owns the model itself. It can give you credits, discounts, capacity commitments and sometimes capabilities you cannot get anywhere else.
The inference provider owns the operational experience. Once you depend on its performance characteristics, configuration and infrastructure, moving isn’t completely free.
And with self-inference, the moat is almost the opposite. You’ve invested in the infrastructure because you want control, predictable economics, data sovereignty or some combination of them.
OpenRouter weakens all three.
Not completely, of course. But enough to create something very valuable: buyer power.
Alex said something that explains this pretty well: a significant part of OpenRouter’s business comes from companies hitting unplanned inference capacity. You might normally buy directly from Anthropic, or run your own inference, because that is cheaper and more predictable. But then you hit a capacity limit, traffic jumps unexpectedly, or you simply need access to a new model before you have time to change your infrastructure.
And thus our revenue is going to be dominated by, you know, the same things that dominated today that dominate it today, which is like in, you know, like us helping people with an unplanned inference capacity.
OpenRouter becomes the overflow layer, and economically that matters more than it sounds. If OpenRouter is repeatedly where companies go when their normal inference path can’t serve them, it collects demand across all three consumption models, and enough demand becomes leverage.
You can already see hints of what that power looks like. OpenRouter currently lists GPT-5.6 Sol at 50% off its reference pricing.
I don’t know how much of that specific discount comes from OpenRouter negotiation versus provider promotion, so I wouldn’t build the entire thesis on a single pricing example. But structurally, aggregating this amount of inference demand gives OpenRouter leverage that an individual startup simply doesn’t have.
The obvious objection is that none of this is why the deal happened. Atallah’s announcement stresses that OpenRouter keeps its name, product, roadmap and neutrality, and some of the people closest to the company have argued the acquisition is really about ecosystem-wide AI security and alignment rather than routing or billing economics. That reading is coherent, and if OpenRouter genuinely stays neutral then some of the buyer power stays with OpenRouter rather than transferring upward. But neutrality and aggregation aren’t in conflict. A neutral marketplace with 10 trillion tokens a day flowing through it still concentrates demand, and Stripe now owns the company that sees it.
Stripe needs that leverage.
If Stripe stays only at the point where dollars enter your company, while model providers increasingly control the economics inside your product, Stripe gets pushed toward the edge again.
You can see the pressure from another direction too. Visa announced a strategic partnership with OpenAI in June to bring Visa’s payment network directly into OpenAI’s agentic commerce experiences.
This market isn’t waiting for Stripe.
If inference companies become the PayPals of token economics, Stripe needs to own the layer above them.
OpenRouter gives them a way to do it.
Inference billing is much uglier than payment billing
There is a second reason OpenRouter matters to Stripe, and it’s less about negotiating power than about developer experience. This isn’t a new direction for Stripe either. It has spent the past year helping companies optimize token costs and route tokens efficiently, shipping products like Token Billing, and OpenRouter was already a Stripe customer for its own payments. The acquisition is a continuation, not a swerve.
Metering AI is not counting tokens. Counting tokens is the easy part, and once you try to build a commercial product on top of those tokens the problem widens fast.
One model has a different tokenizer from another. Input and output tokens have different prices. Cached tokens might have another price. Reasoning might be priced differently. An image is different from text. Video is another world completely.
Then you have the commercial layer of your own product, which usually doesn’t map cleanly to tokens at all. You might sell 10,000 actions to a customer, while one action internally triggers several model calls, possibly across different models with different costs. Add enterprise contracts, committed usage, overages, different entitlement rules, and suddenly the number coming from the model provider is only one input into what you eventually bill.
This is why metering AI gets horizontal very quickly. The hard part isn’t counting the tokens, it is connecting the infrastructure consumption to the unit you actually sold to the customer.
Eventually you need to reconcile what the infrastructure says happened with what you actually billed the customer for.
This is a lot of what we’re dealing with at Stigg around AI usage management. The interesting engineering problem isn’t recording that 2,741 tokens were consumed. It’s maintaining the relationship between consumption, entitlements, pricing and revenue.
Then add another problem: the underlying currency is insanely volatile.
The model that made economic sense for a feature six months ago may be a terrible choice today. Prices drop, context windows change, providers add caching, a new open model suddenly performs well enough for a workload that previously needed a frontier model.
Even the word “token” hides the problem because a token isn’t really fungible. One million tokens of one model and one million tokens of another model are completely different economic units.
That’s uncomfortable if you’re trying to build predictable gross margins.
This is where OpenRouter’s developer experience becomes much more strategic.
Stripe built one of its strongest distribution channels by becoming the thing engineers actually liked integrating. The docs, SDKs and APIs got Stripe into the application early, and once payment infrastructure is wired deeply into an application, replacing it is painful.
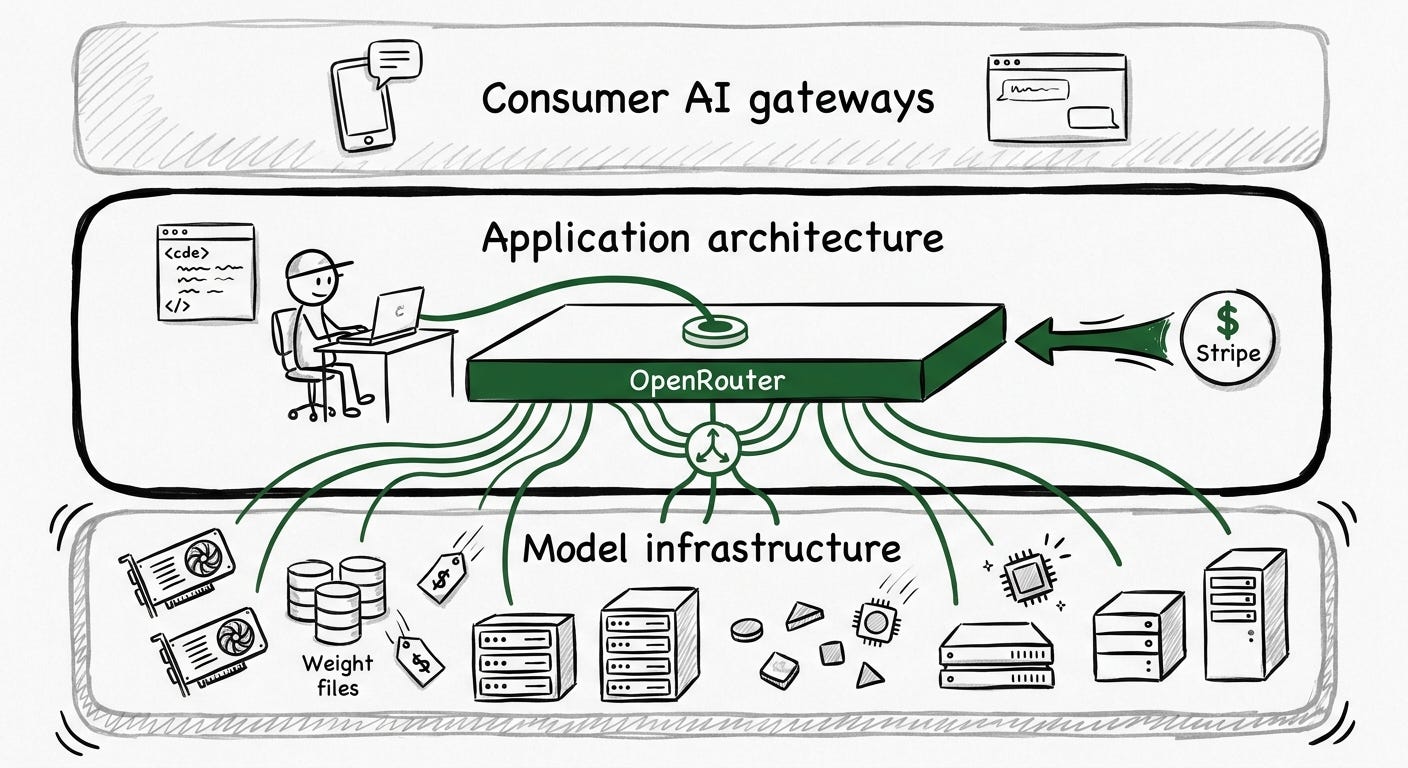
OpenRouter has a similar property. It takes something that changes constantly and gives developers a stable interface.
I can integrate OpenRouter very quickly: start with one model, add another tomorrow, change the underlying provider, and add routing logic around the whole thing without rebuilding the application’s inference layer.
That matters to Stripe because the acquisition puts them much closer to the actual consumption event.
OpenRouter also sits at a useful level in the stack. Go much deeper toward something like Hugging Face, and you’re getting into model infrastructure that I don’t think Stripe wants to operate directly. Go much higher toward consumer-oriented AI gateways, and you’re no longer sitting in the application architecture where developers make these economic decisions.
OpenRouter is almost exactly in the middle.
Deep enough to control model consumption.
Simple enough to look like Stripe.
What Stripe might do with it
This is where I think the acquisition can become much more interesting than routing.
Stripe already knows the money side of an AI company. OpenRouter sits on the other side, where the company is actually spending tokens. Once you have both, you can start doing things that every AI startup manages today on its own.
Loans are one example. Stripe already lends money based on the revenue it sees. But for an AI startup, sometimes the thing you actually need is not another $50K in cash, it is another $50K of inference to launch a feature, run an experiment or survive a spike in usage. Stripe could finance that directly, based on the business it already understands, and get paid back from the revenue later.
The same applies to what is basically currency exchange between models. Not literally, because one token is obviously not equal to another token, but economically this is what companies are doing all the time. A flow that made sense on one model three months ago may now run well enough on another model at half the cost.
Today you need to discover this yourself. OpenRouter sees enough usage across models and providers to potentially predict it. So Stripe could eventually say: this workload is costing you too much, move it here, keep roughly the same result, improve your margin.
That is much closer to how Stripe already thinks about payments. They don’t only process the transaction, they try to improve authorization, fraud, currency handling and all the things around it. OpenRouter gives them a way to do the same thing around inference.
There is also outcome-based pricing, which I think is mostly usage-based pricing with another abstraction on top.
If I charge a customer for a resolved ticket instead of tokens, the customer doesn’t need to care which model I used, but I definitely do. If one resolved ticket costs me $0.80 and another costs $7 because the agent took a different path, I still need to understand the usage underneath the outcome and keep the margin sane.
Every AI company is building a small bank
Billing used to sit more on the edge of the application. You built the product, then somewhere around it you attached subscriptions, seats, or usage.
With AI, the economics are inside the execution path. Every model call costs something, and you need to translate that cost into whatever the customer pays you for: credits, actions, outcomes, API calls, whatever.
So an AI company is managing two economies at the same time. On one side there is the money coming from the customer. On the other side there are tokens, models, providers, discounts and capacity. Somewhere in the middle you need to make sure the conversion between them still leaves you a business.
This is why I think the “Stripe is a bank” analogy is useful here.
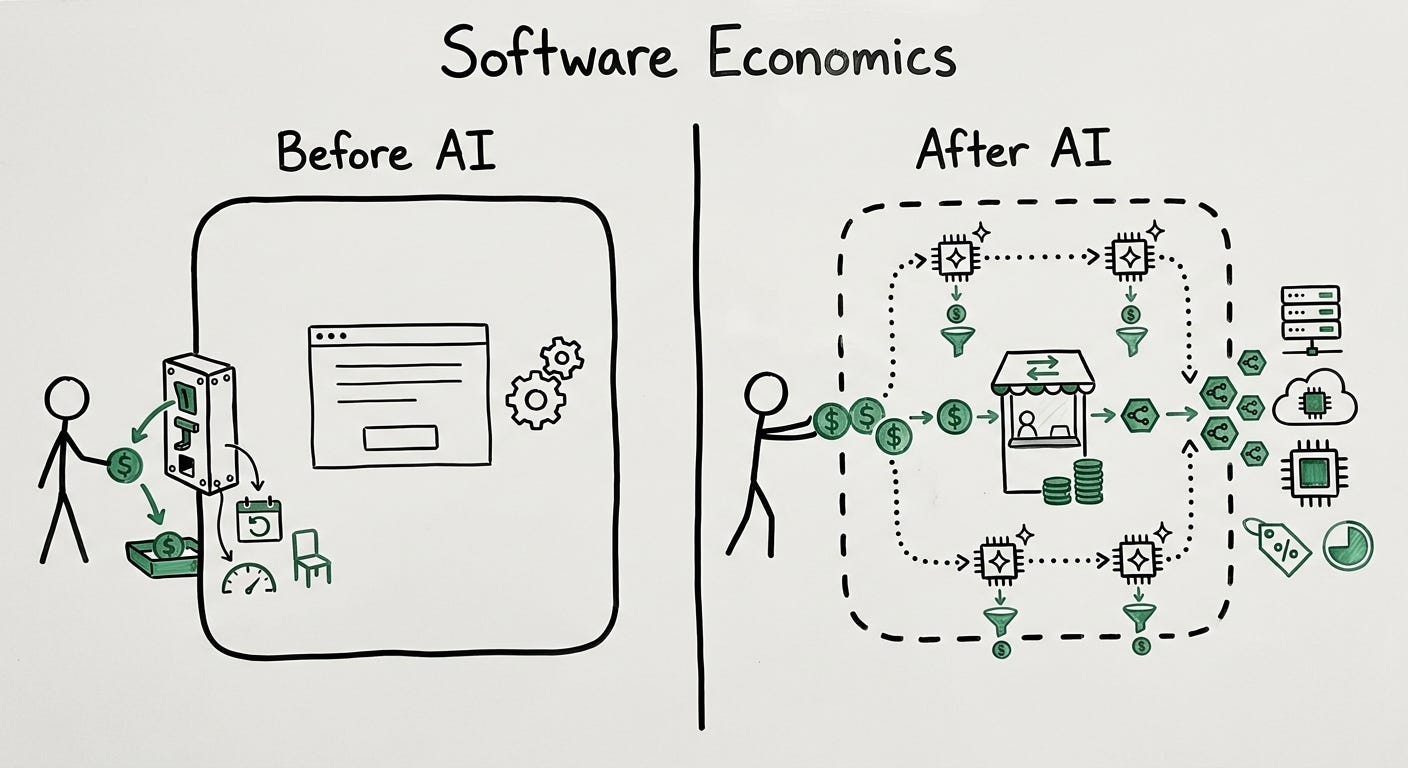
Stripe built the infrastructure around the first economy. OpenRouter gives them a very strong position in the current one.
If tokens really become one of the currencies software companies need to manage, then Stripe buying OpenRouter is much less strange than the internet has made it out to be.
At the end of the day, they are simply trying to make sure you don’t have to build that bank yourself.
The 'routing by itself isn't defensible anymore' point is what most coverage of this deal misses - routers are commoditizing almost as fast as the models they sit in front of. From the buyer's side, the durable form of that buyer power is a workload-to-capability portfolio: every model fails differently, so matching tasks to capability profiles rather than to whichever marketplace you integrated first is what keeps the command layer swappable. The second-order question is whether Stripe can resist making the router itself the product, because that is exactly where the moat inverts.
Good read. Stripe’s gone from helping openrouter collect the money to buying the thing that decides where the money goes.
Looking at it from the zoomed out version of what tech is doing right now - nvidia and hugging face, Cloudflare integrations, vercel - the scramble is to control the control points of model distribution
I did a bit of thinking here - https://substack.com/@movingpartstech/note/c-323633435